
To measure AI agent productivity gains, compare a documented pre-agent baseline against four layers of results: adoption, activity, outcome, and financial impact.
That’s how you measure employee productivity gains from an AI agent without guessing. A gain only counts once it’s priced against the agent’s real cost, hours saved minus oversight time.
Skip the baseline, and you’re guessing, the exact trap our phased AI rollout framework exists to prevent.
Most companies never get this far. McKinsey’s November 2025 State of AI survey of nearly 2,000 organizations found 88% now use AI in at least one function.
Only 6% qualify as “high performers” with a measurable EBIT impact of 5% or more. Adoption solved itself. Proof didn’t.
Quick answer: To measure AI agent productivity gains, track four separate layers, never one blended number:
- Adoption: is the agent being used
- Activity: how much work moved through it
- Outcome: did quality hold or improve
- Financial impact: did it hit the P&L
Subtract oversight time from every hours-saved figure, and check self-reported gains against system data before reporting either one to leadership.
Key Takeaways
- Self-reported and measured productivity are often different numbers. METR’s randomized trial found developers were 19% slower with AI, yet believed they were 20% faster.
- 88% of organizations use AI in at least one function, but only 6% report a measurable EBIT gain, per McKinsey’s 2025 State of AI report.
- Activity can climb while quality collapses in the same rollout. Faros AI’s 2026 study found throughput up 33.7% alongside code churn up 861%.
- 77% of employees using AI say it added to their workload, even though 96% of leadership expected a productivity gain, per Upwork Research Institute.
- Boards now expect dollars, not hours. Futurum Group’s 2026 survey found financial impact nearly doubled as the top ROI metric.
- Two forms of gain get conflated: one person doing more work, and one person making everyone else’s work better. They need separate metrics, covered below.
What “Productivity Gain” Actually Means Before You Measure Anything
Ask five people in the same company whether the AI agent is working, and expect five different answers. Each one is usually correct about a different slice of the data.
Confusion starts even earlier, with what actually counts as an agent versus simple automation. Confirm that first with our AI agent vs. no-code automation comparison.
Production vs. Productivity: The Distinction Almost Everyone Skips
Production is the amount of work completed. Productivity is that output divided by what it cost to produce.
Confusing the two is the single most common measurement mistake in AI rollouts.
A support agent resolving 40% more tickets per week is production. If those tickets now take twice the review time, productivity may have actually fallen.
The number that looks good in a status update isn’t automatically the number that reflects reality. Every framework below exists to stop the two from getting confused.
The Perception Gap: Why Self-Reports and Measured Data Rarely Match
METR’s July 2025 trial is the clearest evidence available here. Sixteen experienced open-source developers completed 246 real coding tasks.
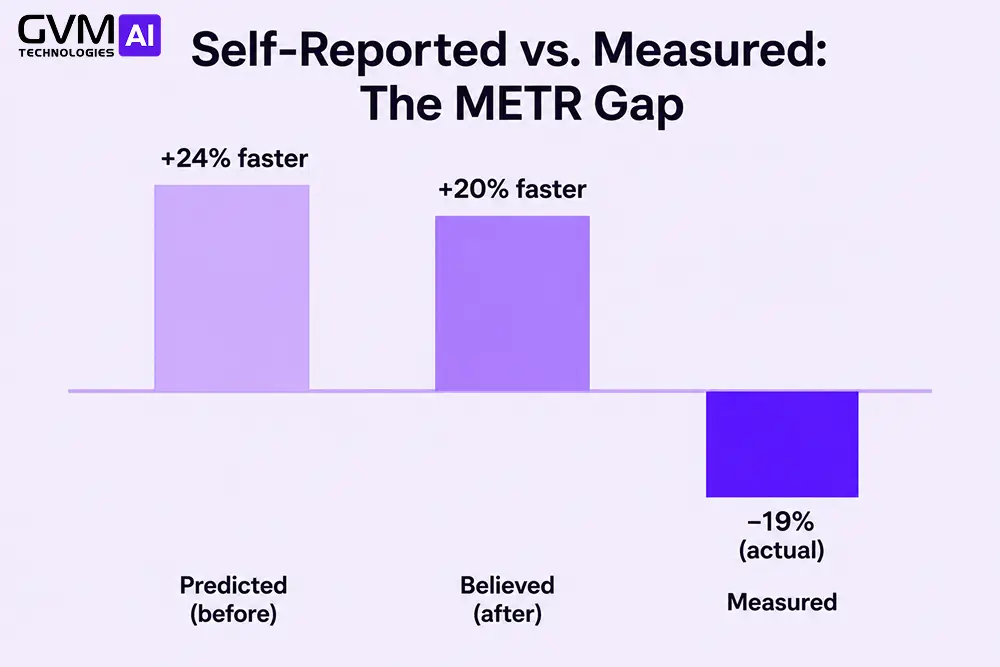
Half worked with AI tools, half without, assigned at random, the same method used in clinical drug trials.
- Before starting: developers predicted AI would make them 24% faster
- After finishing: they estimated AI had made them 20% faster
- What actually happened: they were 19% slower
METR has since called this specific result dated, since tools have moved on. The underlying pattern hasn’t.
METR’s own 2026 follow-up survey of 349 technical workers still found a roughly 40-point gap between believed and measured output.
A feeling of speed and a measured rate of speed are two different data points. Only one belongs in a board deck.
Closing that gap starts with fit. Our AI agent readiness checklist scores seven factors, including data quality and ownership, before you measure anything.
The Productivity Proof Pyramid: How to Measure AI Agent Productivity Gains in 4 Layers
Most measurement efforts stop at the two easiest layers to pull data for. Those also happen to be the two layers a CFO finds least convincing.
| Layer | What It Measures | Example Metrics | What It Proves | What It Misses |
|---|---|---|---|---|
| Adoption | Is the agent being used | Active users, sessions/week, % of tasks routed to the agent | People are touching the tool | Whether the work improved |
| Activity | How much work moved through it | Tasks completed, calls answered, documents processed | Volume is up | Whether quality held or need was even there |
| Outcome | Did the work get better | Cycle time, error rate, resolution rate, rework rate | The work itself improved | The connection to actual money |
| Financial | Did it hit the P&L | Cost per case, headcount reallocated, revenue captured | The number leadership signs off on | Slowest layer to appear |
Layer 1: Adoption Metrics Tell You Almost Nothing on Their Own
Adoption answers a gatekeeping question, not a productivity question: is anyone using this tool?
Track it anyway. 12% adoption and 90% adoption point to very different problems.
For the mechanics of adoption itself, see our guide on training a team to work alongside an AI agent.
Layer 2: Activity Metrics Can Lie by Omission
This is the layer where “the agent is clearly working” gets said out loud, based on a number that only tells half the story.
Faros AI’s 2026 report analyzed two years of telemetry across 22,000 developers and 4,000+ teams. Under high AI adoption:
- Task throughput per developer rose 33.7%
- Epics completed per developer rose 66%
- PR merge rate rose 16.2%
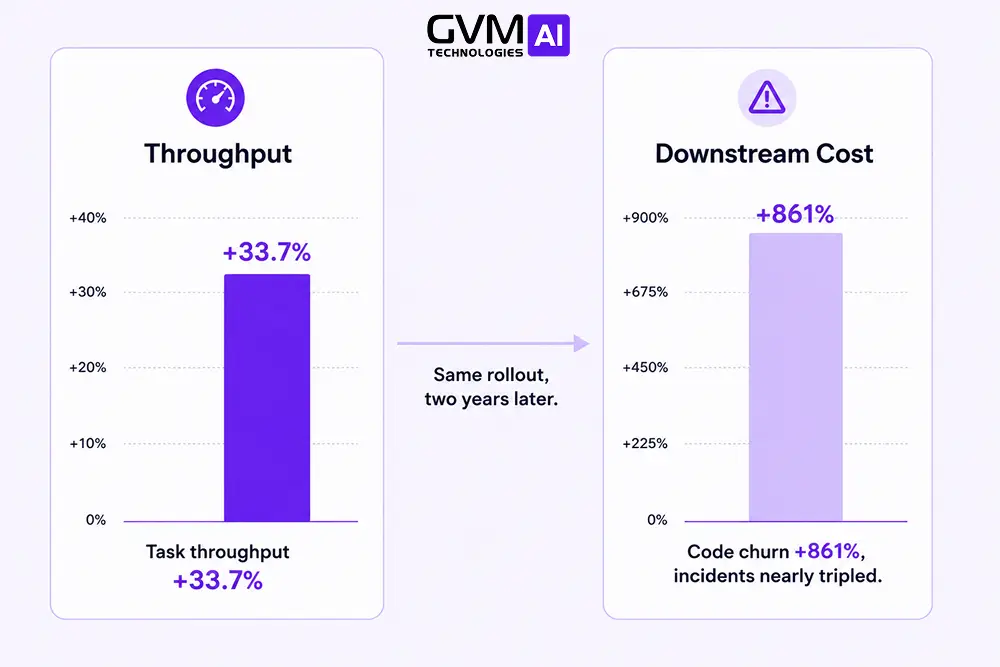
Read alone, that’s a clean productivity story. Read alongside the same report, it’s a warning:
- Code churn (deleted vs. added code on merged work) rose 861%
- Incidents-to-PR ratio nearly tripled
- Bugs per developer rose 54%
- Median review time increased 5x
Faros calls this the “Acceleration Whiplash.” Throughput accelerated, and so did the cost showing up two steps downstream.
A calling agent handling more calls per hour isn’t more productive if escalations climb at the same pace. Activity proves work moved. It doesn’t prove it stayed moved.
If an agent’s own log claims success but a downstream check finds otherwise, that’s a hallucination risk. Our AI agent hallucinations in production guide covers what unreviewed output has already cost real companies.
Layer 3: Outcome Metrics Are Where Real Signal Shows Up
Outcome metrics ask whether the work got better, independent of how much of it there was:
- Cycle time
- Error rate
- Resolution rate
- Rework rate
- Customer satisfaction
If activity is up and these hold steady or improve, the gain is likely real.
If activity is up and these degrade, someone (or something) is trading quality for a number that just reads well in a meeting.
Layer 4: Financial Impact Is What Leadership Wants Now
This layer used to be optional. It stopped being optional in 2026.
Futurum Group’s 2026 survey of 830 IT decision-makers found:
- Direct financial impact nearly doubled to 21.7% as the top ROI metric
- Pure productivity gains fell 5.8 points as the leading success measure
A productivity claim without a dollar figure attached stopped being enough on its own. Layer 4 metrics include:
- Cost per resolved case
- Headcount reallocated to higher-value work
- Revenue captured that would have been lost
- Overtime spend that stopped
The worked ROI example below shows how to build this figure from the layers above it.
Direct Productivity vs. Leveraged Productivity: The Framework Most Companies Miss
Two employees can each show a strong AI-driven number and still create very different amounts of value for the business.
Why Direct Output Alone Rewards the Wrong Behavior
Direct productivity is what one person personally produces: tickets closed, calls handled, documents processed. It’s the easiest number to pull.
Traditional performance systems default to rewarding whoever has the highest one.
Leveraged productivity is different, how much a person improved the system itself:
- A better prompt that cut error rates for the whole team
- A workflow fix that raised the agent’s accuracy for everyone downstream
- Documentation that stopped a recurring escalation
That value depends on what the agent retains and reuses. Our guide to AI agent memory and context covers exactly that layer.
Improve memory once, and every future user benefits, yet none of it shows up under one person’s name on a dashboard.
How to Spot and Credit Leveraged Productivity
An employee who resolves fewer cases but raises agent accuracy 5% across a 20-person team likely creates more total value than the top individual closer.
Most companies never see this, because their dashboards only track direct output. Ask three questions instead:
- Did this person improve the agent’s accuracy or reduce a specific error pattern?
- Did they document a rule or exception the whole team now uses?
- Did their fix reduce escalations or rework for anyone besides themselves?
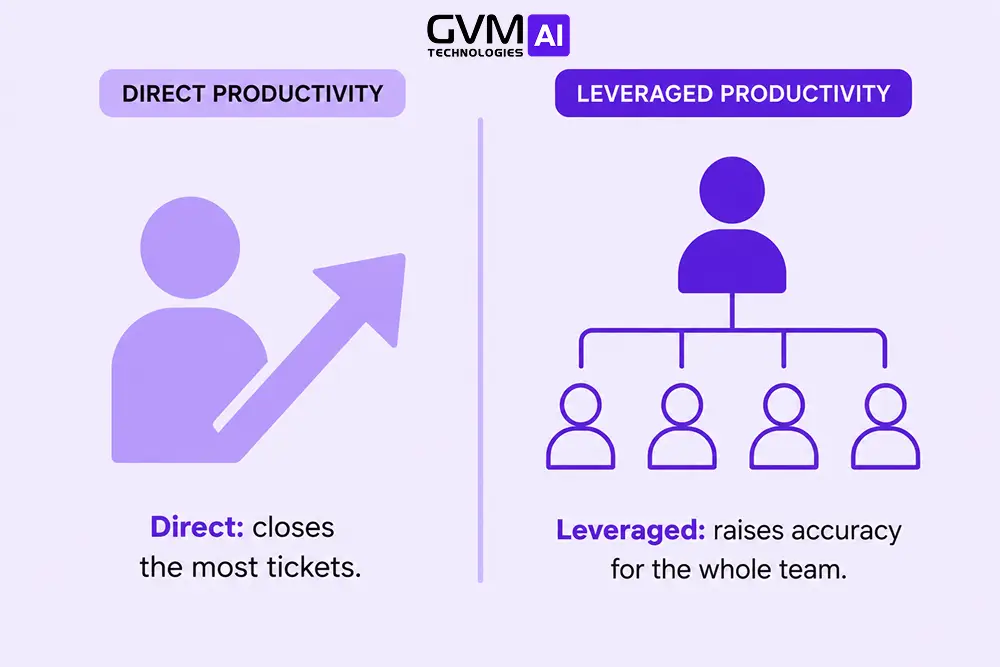
Reward both forms of productivity explicitly. Otherwise, the people most likely to strengthen the system quietly stop bothering.
Set a Real Baseline Before the AI Agent Goes Live
Skip this step, and every number afterward is a guess with a decimal point attached.
MIT’s 2025 “GenAI Divide” research covered 52 executive interviews, 153 leader surveys, and 300 deployment analyses. It found 95% of enterprise pilots showed no measurable P&L impact.
Most of that failure traced back to measurement gaps, not model quality.
1. What a Usable Baseline Actually Includes
A usable baseline is specific and boring. Document these in numbers before the agent touches the workflow:
- Time: hours per week a human currently spends on the task
- Cost: the fully loaded hourly cost of that person, not base wage alone
- Volume: how many of these tasks happen weekly, and how much that swings
- Quality: current error rate, rework rate, or complaint rate
- Speed: current average and worst-case turnaround time
Four to eight weeks of clean baseline data beats any vendor benchmark. It’s built from your actual exceptions, not someone else’s average customer.
See what this looks like in production in our customer outreach case study, where the baseline was set before launch.
2. Baseline Mistakes That Wreck the Measurement Later
- Measuring the “ideal” manual process instead of what actually happens, workarounds included
- Using an industry average instead of your own numbers
- Skipping quality entirely, so a speed gain that trades away accuracy looks like a pure win
- Starting the clock after word gets out that AI is coming, which changes behavior early
3. Isolate the AI Variable From Everything Else That Changed
This mistake goes uncaught for months. Companies often deploy an agent the same time they trim a team or restructure a department.
Or add a second agent to the same workflow, the exact overlap our guide to single-agent vs. multi-agent systems addresses.
When the number looks good, leadership credits the AI. Some of that gain is real.
A meaningful share is often just reduced coordination overhead, fewer people means fewer meetings and less approval friction, independent of what the agent did. Separate the two:
- Note every headcount or process change inside the same measurement window
- Ask whether the gain would show up even without the AI agent at all
- If unclear, treat the number as directional until a full quarter of stable data comes in
The AI Agent Productivity ROI Formula, With a Worked Example
Once the baseline and four-layer data exist, here’s how to calculate ROI: simple arithmetic, once you know what to subtract.
The Formula and Its Most-Skipped Line Item
AI Agent Productivity ROI (%) = [(Hours Saved × Fully Loaded Hourly Cost) − Total Cost of the Agent] ÷ Total Cost of the Agent × 100
Total Cost of the Agent adds up four things most quick calculations only include one or two of:
- Subscription or licensing cost
- Implementation and integration cost
- Ongoing oversight and review time, paid at the reviewer’s hourly rate
- Training time
That third item, oversight and review time, is the piece almost every back-of-napkin calculation skips.
It’s also the exact mechanism behind the automation paradox: hours freed on one side get quietly consumed by review on the other.
Freed time that never gets redirected doesn’t disappear from the ledger. It just stops counting as a gain.
The same happens to a saved hour absorbed into slower, lower-value work. It never reaches the P&L either.
Track the payback period alongside the percentage, too. A 50% ROI that takes 18 months to arrive is a different decision than the same return in 3.
A Worked Example: AI Calling Agent for a Real Estate Brokerage
A 12-person brokerage deploys an AI calling agent for after-hours and overflow calls that used to go to voicemail.
| Line Item | Value |
|---|---|
| Baseline: hours/week staff spent on calls the agent now handles | 15 hours |
| Fully loaded hourly cost of that staff time | $30/hour |
| Gross annual value of hours freed (15 × $30 × 52) | $23,400 |
| Agent subscription cost (annualized) | $7,200 |
| One-time integration cost | $2,000 |
| Manager review time on flagged calls (3 hrs/week × $40/hr, annualized) | $6,240 |
| Total annual cost of the agent | $15,440 |
| Net benefit ($23,400 − $15,440) | $7,960 |
| ROI ($7,960 ÷ $15,440 × 100) | ≈ 51.6% |
That’s a real, defensible, modest number, not a hype figure. It also survives the question “did you include Dana’s review time?” Because it did.
What Counts as Financial Impact (It’s Broader Than Cost Savings)
Most teams default to cost avoidance as the only financial metric. That leaves real value uncounted.
Cost-Avoidance Metrics
- Overtime and contractor spend eliminated
- Headcount reallocated to higher-value work instead of cut outright
- Rework and error-correction cost avoided
- Missed-call or missed-lead revenue recovered
Revenue and Opportunity Metrics AI Agents Can Surface
An agent processing large conversation or document volumes can surface patterns a manual process never had time to catch:
- A recurring objection worth a new sales script
- A support pattern that points to a product fix
- A lead segment converting at twice the average rate
The strongest board-ready ROI case isn’t only “we saved time.” It’s the new revenue idea the agent’s data surfaced and got into next quarter’s plan.
Log these separately from efficiency gains. They’re a different category of value, and conflating the two makes both numbers harder to defend.
Metrics by Function: What Productivity Means Role by Role
A single dashboard hides more than it reveals. The right KPIs for one workflow are the wrong KPIs for another.
| Function | What the Agent Does | Core Metric | Where the Data Lives |
|---|---|---|---|
| Inbound calls / scheduling | Answers, triages, routes, books | Calls resolved without a transfer, missed-call recovery rate | Calling platform logs, calendar |
| WhatsApp / chat lead intake | Qualifies leads, answers FAQs | Time-to-first-response, lead-to-qualified rate | CRM, WhatsApp Business API logs |
| CRM data entry and updates | Logs activity, enriches contacts | Manual entry hours removed, stage-advance lag | CRM audit log, time tracking |
| Document processing | Extracts, routes, flags exceptions | Documents/hour, exception rate, time-to-decision | Document management logs |
None of these are adoption metrics. Each ties to a change your team can already see inside a system it already owns.
Our own CRM automation and email outreach work tracks the CRM row the same way, against a documented baseline.
How Long to Wait Before You Trust the Numbers
Measuring once isn’t enough. You need to measure AI agent productivity gains over time, not just at launch.
That raises two questions: how soon can you get a first read, and how soon can you trust it.
When You Get a First Directional Read
A first directional read is usually possible in 4 to 8 weeks, enough volume to smooth out normal week-to-week noise.
When the Number Is Stable Enough to Present
A number stable enough for leadership needs 8 to 12 weeks, long enough to survive a full billing cycle, a slow week, and a busy week.
That lines up with the pilot-to-scale window in our phased AI rollout framework. The gates that make a rollout safe are the same checkpoints that make measurement possible.
Measuring on day three and calling it a verdict is the fastest way to produce a number nobody trusts six weeks later.
Common Mistakes That Wreck Productivity Measurement
Most bad AI productivity numbers aren’t caused by bad AI. They’re caused by measurement decisions made before the agent ever went live.
- Reporting a vanity metric as if it were a KPI. Calls handled or messages sent measures production, not productivity.
- Skipping the baseline. Without a documented “before,” there’s no honest “after.”
- Letting the agent grade its own work. A separate check catches what its own log won’t.
- Ignoring oversight and review time. Every hour a human spends double-checking the agent belongs on the cost side.
- Not isolating the AI variable. Layoffs or restructuring in the same window inflate the apparent gain.
- Letting freed time evaporate. Time the agent frees up has to be redirected, or the gain quietly disappears.
- Measuring once and calling it settled. A number pulled in week two misses the quality drift Faros AI documented over two years.
- Turning the metric into individual surveillance. People start optimizing the number instead of the outcome, and the data stops being trustworthy. Our guide to rolling out an AI agent without employee pushback covers why this backfires.
- Reporting hours saved to an audience that expects dollars. “We saved 400 hours” lands differently than “we avoided $46,000 in overtime,” even describing the same gain.
How to Present Productivity Gains to Leadership Without Getting Picked Apart
Two rollouts with identical outcomes can get two very different receptions. The difference is usually the unit the result is reported in.
Translate Every Metric Into a Dollar Figure First
Do this before the meeting, not during it. “Resolution time dropped 22%” is a real result.
“Resolution time dropped 22%, worth roughly $31,000 a year in avoided overtime” is the sentence that survives a budget review.
Show the Math, Not Just the Number
Include the ROI formula’s components, oversight cost and all, not a single headline percentage.
A number leadership can’t audit is a number they’ll eventually distrust. If this is more than your team has bandwidth for, that’s a legitimate build-versus-buy question.
Our comparison of an AI agency versus an in-house AI team covers when outside expertise pays for itself.
Tools and Data Sources You Actually Need
Most small and mid-market teams don’t need a new analytics platform. They need four sources that already exist:
- The system of record the workflow lives in (CRM, calling platform, document system), for volume and cycle-time data
- Time-tracking or manager estimates for the baseline and ongoing oversight hours
- The agent’s own action logs, treated as a starting point, never the final word
- A short recurring employee survey, kept narrow and never tied to individual reviews
Log exactly what data each source exposes the agent to. Our guide to giving an AI agent access to customer data covers that boundary.
A dedicated observability layer earns its cost once volume outgrows manual spot-checks. Buying one before that adds cost without adding clarity.
Real Gain or Gamed Gain: How to Tell the Difference
Look at activity and quality together. Never one without the other.
| Signal | Real Gain | Gamed or Hollow Gain |
|---|---|---|
| Activity metric | Up | Up |
| Quality/error metric | Flat or improving | Also rising |
| Review/rework time | Flat or shrinking | Quietly growing |
| Employee self-report | Roughly matches measured data | Runs well ahead of measured data |
| Escalations to a human | Flat or falling | Rising, buried in a different dashboard |
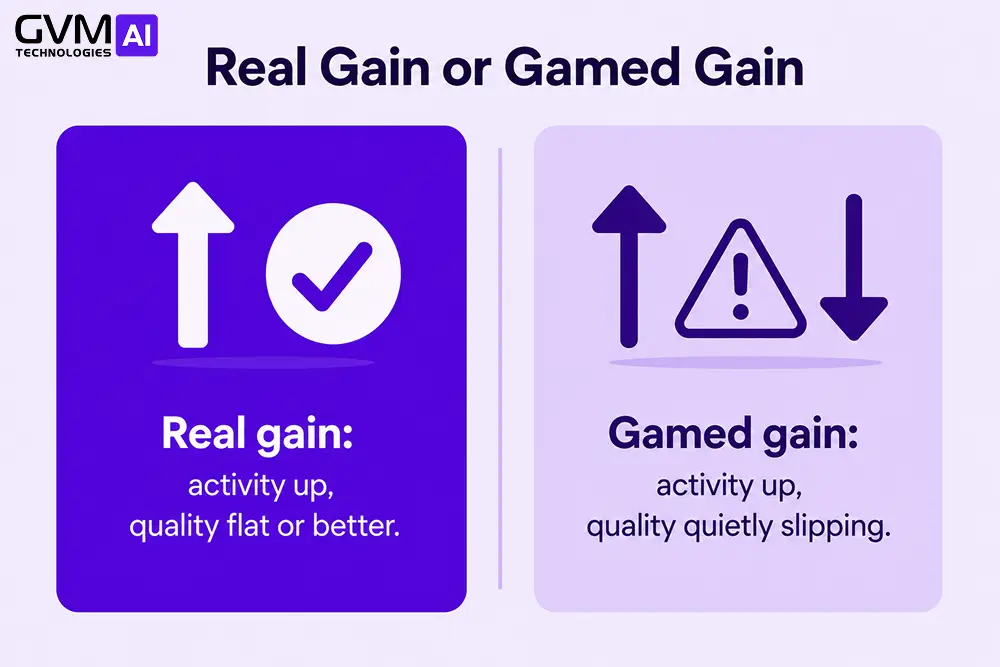
A genuine gain moves activity and quality in the same direction.
A hollow one shows activity climbing while another row quietly moves the wrong way. That’s the pattern behind most of MIT’s 95% figure.
There’s one more place unmeasured work hides. Only 40% of companies had official AI subscriptions, per MIT’s research.
Yet 90% of employees were already running work through personal tools, what researchers now call the shadow AI economy.
If your official numbers look flat, check whether the real work is happening through tools you’re not measuring. Our guide to shadow AI in the workplace covers what that costs.
FAQs About Measuring AI Agent Productivity
1. What’s a realistic productivity gain to expect from an AI agent?
It varies by workflow. Well-scoped, high-volume tasks like missed-call recovery or lead intake tend to land in the 20 to 50% range once oversight time is subtracted. Broad, vague deployments almost never produce a number this clean.
2. How long does it take before productivity gains are actually measurable?
A first directional read is usually possible in 4 to 8 weeks. A number stable enough to present typically needs 8 to 12 weeks across a normal mix of busy and slow periods.
3. Why do employees report bigger AI productivity gains than the data shows?
Perceived effort and measured effort aren’t the same thing. METR’s randomized trial found developers estimated a 20% speed gain from AI while measured data showed a 19% slowdown on the same tasks.
4. Should we measure hours saved or dollars saved?
Track both, but lead with dollars in front of leadership. Futurum Group’s 2026 data found direct financial impact nearly doubled as the top ROI metric enterprises use to justify continued AI spend.
5. What if activity metrics go up but quality metrics go down?
Treat that as a warning sign, not a win. It’s the exact pattern Faros AI documented across 22,000 developers: throughput up, code churn up 861%, incidents nearly tripled.
6. Do small businesses need the same measurement rigor as large enterprises?
The scale is smaller, but the method is identical. Small teams often move faster since ownership is clearer. A five-person team can usually name a workflow, an owner, and a review cadence in one conversation. Many lean on a partner instead of building this from scratch. Our overview of what an AI automation agency actually does covers that trade-off.
7. What’s the actual difference between AI adoption and AI productivity?
Adoption measures whether people use the tool. Productivity measures whether the work got better because of it. The two numbers can, and often do, move in opposite directions.
8. Can we rely on employee self-reports alone?
No, but don’t ignore them either. Pair a short, non-punitive survey with hard data from your system of record. Self-reports catch friction dashboards miss; system data catches the precision self-reports miss.
9. What tools do we need to measure AI agent productivity?
Most SMB rollouts can start with data already in the CRM, calling platform, or document system, plus basic time tracking and a short survey. Dedicated observability platforms earn their cost once volume outgrows manual checks.
10. How do we present productivity gains to leadership?
Convert every metric into a dollar figure before the meeting. Show the ROI formula’s components, including oversight cost, and be upfront about what the baseline covered.
11. Is a productivity gain that doesn’t show up in profit still worth keeping?
Sometimes, if it improves something leadership has explicitly agreed matters, like response time or retention on a burnout-prone task. Make that call deliberately, not as a fallback when the financial math didn’t work.
12. What’s the single biggest mistake companies make measuring this?
Skipping the baseline. Every other mistake on this list is easier to catch when there’s a real “before” to compare against.
Conclusion
To measure AI agent productivity gains accurately, you need more than a feeling and more than a login count.
An AI agent can genuinely make your team faster. It can also make it slower while everyone believes the opposite.
Sometimes both happen at once, on different parts of the same workflow. The only way to know which is happening is to measure something more specific than a feeling, and more complete than a login count.
Build the baseline before the agent goes live. Track adoption, activity, outcome, and financial impact as four separate layers, not one blended number.
Subtract oversight time from every hours-saved calculation. Credit leveraged productivity alongside direct output.
Check self-reported numbers against system data instead of trusting either alone.
When it’s time to report the result, lead with a dollar figure you can defend line by line, not a headline percentage nobody can audit.
Ready to Prove What Your AI Agent Is Actually Worth?
Most companies don’t have an AI productivity problem. They have an AI measurement problem: deploying real systems, then guessing at the results because nobody built the baseline first.
GVM Technologies AI scopes every deployment with the baseline and metrics defined before launch, not after someone asks for proof:
- AI agent deployments
- Calling agents and WhatsApp CRM
- Full workflow automation
That’s the same discipline behind our customer outreach case study, where the measurement plan was built before launch, not requested after.
Talk to our team about what a real baseline for your workflow should look like, before you spend another month guessing at the ROI.