
Your AI agent stopped working after a model update because the model changed and the code wrapped around it did not.
That gap, not the model itself, is almost always the real cause.
An agent is not just a model. It is a system prompt, tool definitions, memory, and retry logic that were all tuned to one model’s habits.
A newer version breaks those habits without an error message. The agent keeps running and keeps looking fine while it does the wrong thing.
Quick answer: An AI agent breaks after a model update when the wrapper around it, the prompt, the output parser, the tool format, and the retry loop, still expects the old model’s behavior. The fix is to find the layer that broke and repair it, not to switch models again. Roll the model back first to confirm the model is even involved.
Key Takeaways
- The model is the trigger, not the cause. The break is almost always in the scaffolding around it.
- A model changes two ways: you upgrade it, or the provider moves a “latest” alias underneath you.
- Most breakage is silent. Gartner expects over 40% of agentic AI projects to be scrapped by 2027.
- A stronger model rarely helps. Reviews of production agents show better models leave most failure modes untouched.
- You can find the broken layer in under 60 minutes, then prevent the next one with a pinned version and 20 to 50 saved test tasks.
A Model Update Means One of Three Things
When an AI agent stopped working after a model update, one of three things changed. Each case has a different fix, so name it first.
1. You Upgraded the Model on Purpose
Someone pointed the agent at a newer version, such as one GPT release to the next or one Claude Sonnet to the next. This change has a date and shows up in a config file or deploy log.
If behavior shifted the same day as a release you shipped, start here. This is the easiest case to prove and reverse.
2. The Provider Changed the Model Underneath You
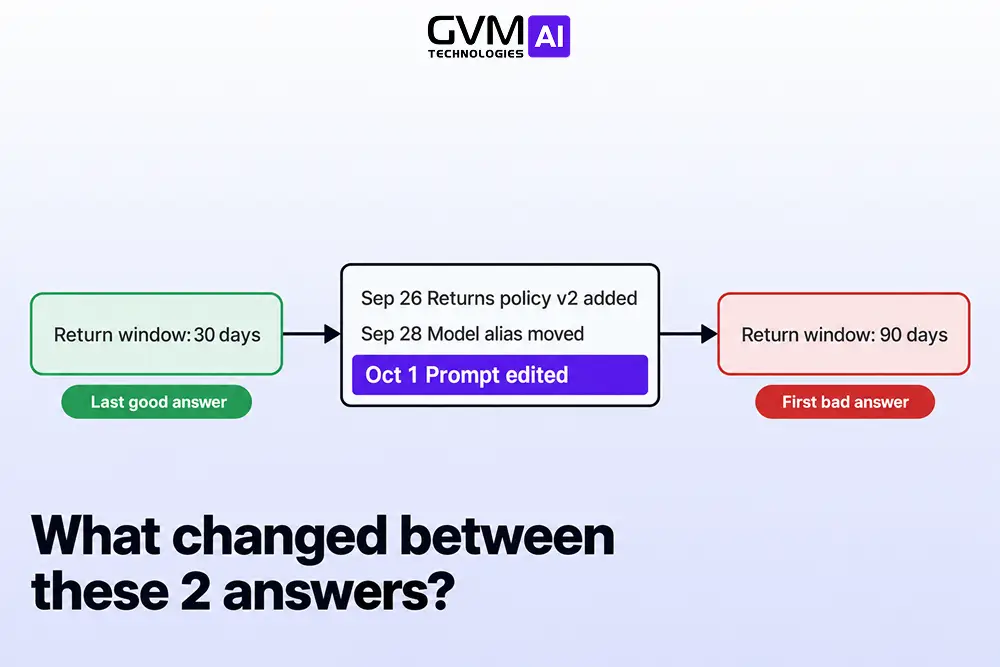
If your agent calls a floating alias instead of a pinned, dated snapshot, the provider can move that alias to a new model or adjust its safety tuning. Your config never changed.
Your agent’s output changed anyway. There is usually a changelog entry, but no one emails you about it.
3. Something Else Broke at the Same Time
A dependency upgrade, an expired token, or a workflow tool like n8n can start producing output that the model API rejects. The model update is a coincidence taking the blame.
Teams lose days here because they compare their own commits and find nothing. The change was somewhere else.
| Signal | You upgraded | Provider changed it | Coincidental break |
|---|---|---|---|
| Shows in your deploy log | Yes | No | Sometimes |
| Matches a provider changelog entry | Maybe | Yes | No |
| Fixed by rolling the model back | Often | Often | No |
| Prevented by pinning a version | Not needed | Yes | No |
The Five Layers Where an Agent Actually Breaks
An agent is a stack. When it stops working, one layer broke. Naming it tells you who fixes it and how fast.

1. The Model Layer
The weights behind the large language model genuinely changed: new training, new safety tuning, a different default verbosity. This is real, and it is the layer people over-blame.
A model that scores higher on public benchmarks can still be worse at your one task if that task leaned on a quirk of the old version.
2. The Harness Layer
The harness is the glue: the system prompt, the parser that reads model output, the format your tools are described in, and the routing logic. It breaks constantly on updates because it was shaped around the old model.
One team saw an agent fail basic tool calls right after an upgrade, purely because the prompt never told the new model that the function schema had changed.
3. The Context Layer
This is everything loaded into each turn: the full tool catalog, retrieved documents, chat history, and memory. Teams pile up 40 or more tools and load all of them every turn.
Trimming to the few tools a query needs has cut token use 70 to 85 percent and raised accuracy at the same time. An update is often when that bloat finally bites, and it is a memory and context design gap.
4. The Tool Layer
The functions and APIs the agent calls. A tool that returns an empty list after a token expired makes the agent confidently report “nothing to do.”
This layer often breaks on its own, and a nearby model update gets accused. It is the same root cause behind many AI agent hallucinations in production.
5. The Infrastructure Layer
Authentication, retries, timeouts, and deploy pipelines. This is the most literal “stopped working.”
Agents running inside an IDE plugin have lost their auth after the plugin updated and returned a flat 401 error, with the model completely uninvolved.
| Layer | What breaks after an update | Who fixes it |
|---|---|---|
| Model | Reasoning style, verbosity, refusals | Provider, or you roll back |
| Harness | Output parsing, tool format, prompt logic | Your engineers |
| Context | Tool routing, “forgotten” instructions | Your engineers |
| Tools | Empty results read as success | Integration owner |
| Infrastructure | Auth, stuck jobs, runaway retries | Your ops team |
What To Do When Your AI Agent Stopped Working After a Model Update
If your AI agent stopped working after a model update, run this 5-step check top to bottom. Most teams find the problem in the first three steps, in under 60 minutes.

1. Confirm Something Actually Changed
Check your deploy history for the window when behavior shifted. Then check the provider’s changelog, status page, and deprecation notices for that same window.
Also check the version of any tool, plugin, or framework the agent runs inside. You are looking for any change on any side.
2. Reproduce One Failure by Hand
Take one task the agent now gets wrong. Run it yourself, step by step, in a plain chat with the same model and the same prompt.
Works by hand but fails in the agent points at the harness or context, not the model. Fails by hand too puts the model or the prompt in play.
3. Read One Full Run Log
Not the agent’s summary of what it did. The raw log: every tool call, the exact arguments, and the exact response.
An agent’s own account of a failure is unreliable and will blame the wrong thing with full confidence.
4. Roll the Model Back and Retest
If you can point the agent at the previous version, do it and rerun the same tasks. Fully fixed means a model or model-plus-harness issue.
Still broken means the problem is in context, tools, or infrastructure. This one test saves the most time.
5. Check the Silent Failures
Expired auth tokens. Tool responses that succeed but return nothing. An API that changed its schema. A reasoning parameter the new model now requires.
None of these throw an error, which is exactly why they reach production and survive there.
The Silent Regressions That Cost the Most
Often an AI agent stopped working after a model update and nobody noticed for weeks, because a crashed agent throws an error and a drifting agent does not.
That second failure costs more, since a customer usually finds it first, not your dashboard.
1. Drift That Never Throws an Error
After an update, watch for tone shifting across the board, estimates now stated as hard facts, or edge cases the agent used to escalate getting resolved instead.
Nobody can settle “is the new model worse” by feel, because feel compares it against a memory. You need a fixed set of tasks to compare against.
2. Actions That Succeed on Paper Only
A tool call returns a success code, the agent logs “done,” and the record never changed. A task-success dashboard counts this as a win.
The fix is to read the target system back after every write and confirm the change landed. Trust the database row, not the agent’s wording. This is the discipline behind measuring real AI agent productivity.
3. Retry Loops That Burn Budget
One team’s runtime retried a rejected tool call over 1,200 times across 16 hours. No crash fired, because a retrying agent is not a dead agent.
A timeout is not a failure. It is missing information, and an agent that guesses instead creates duplicate charges or duplicate emails.
| Symptom after an update | Likely layer | Business cost |
|---|---|---|
| Longer, more cautious replies everywhere | Model | Slower responses, higher token bills |
| Wrong tool for an obvious request | Context | Wrong actions, more human cleanup |
| Parser fails 1 run in 10 | Harness | Silent data gaps, no pattern |
| “No results found” on known-good queries | Tools | Work skipped, reported as done |
| Job never finishes, cost climbs | Infrastructure | Budget drain while dashboards stay green |
Stop the Next Model Update From Breaking Your Agent
You cannot stop providers from shipping updates. You can stop them from being a crisis.
A check of the scaffolding every four to six weeks keeps these incidents small and boring.
1. Pin the Model Version
Call a dated snapshot, not a floating “latest” alias. Update it on your schedule, after testing, not on the provider’s.
Both OpenAI and Anthropic publish deprecation timelines, so you always know your deadline to move.
2. Keep a Frozen Test Set of Real Tasks
Collect 20 to 50 tasks the agent already handles correctly, drawn from your highest-stakes workflows and your worst past incidents. Record the exact input and the real correct outcome, such as “a $40 refund was issued to order 1182.”
Re-run this set before every model change. It is lightweight evaluation and does not need an ML team. Score the workflow first with the AI agent readiness checklist.
3. Grade the Result, Not the Transcript
A test that checks “did the agent say it booked the meeting” is blind to “the meeting was never booked.” Point your checks at the sent email or the updated field.
This catches the exact failure class that model updates introduce most often: confident output, wrong result.
4. Cap Retries and Alert on “Stuck”
Set a hard limit on attempts and total run time. Alert on “running but not progressing,” not only on crashes.
This is standard practice when you plan a phased AI rollout instead of a full launch.
| Habit | Effort to set up | What it prevents |
|---|---|---|
| Pin a dated model version | Under 1 hour | Silent provider-side changes |
| Frozen test set of 20 to 50 tasks | 1 to 2 days | Regressions reaching customers |
| Read-back after every write | 2 to 5 days | “Succeeded on paper” failures |
| Retry and run-time caps | Under 1 day | 16-hour budget drains |
What Fixing It Costs and How Long It Takes
Rough guidance for a reasonably built agent.
- Re-authenticate a plugin or connection: under 1 hour.
- Loosen a strict output parser: half a day to 2 days.
- Rework tool definitions for a new provider: 2 to 5 days.
- Trim context and add per-query tool selection: 2 to 5 days.
- Full scaffolding audit after a major version jump: 1 to 2 weeks.
- The expensive path: switch models again, hope, and pay later in cleanup and lost trust.
Switching providers is not a free swap. Moving between GPT, Claude, and Gemini keeps your logic but usually not your harness, because each model handles tools, prompts, and refusals differently.
Get a Straight Answer From GVM Technologies AI
If your AI agent stopped working after a model update, the cause is specific and findable, and it is almost never the model.
GVM Technologies AI builds and maintains the stability layer that keeps agents running through model changes, whether you run them with an outside partner or an in-house team.
A free agent health check gives you:
- The full trace of one real failed run, with the broken layer named.
- A list of every model alias your agent calls and whether it is pinned.
- A frozen test set built from your real traffic that you keep and own.
- A scoped fix with a timeline, or an honest call to roll back for a month.
Book a free agent review. No pitch, just a specific read on what broke and what it takes to fix it.
FAQs
1. My AI agent stopped working after a model update. Is the new model worse, or is it my setup?
Usually the setup. Roll the model back to the previous version and rerun the same failing tasks. If they pass, the model was fine and your harness or context broke against the new behavior.
2. How do I know if my provider changed the model without telling me?
Check whether your agent calls a dated snapshot or a floating “latest” alias. Then match the date your behavior shifted against the provider’s changelog. Config unchanged plus a changelog entry on that date is your answer.
3. Should I roll back to the old model?
Roll back if the old version is supported for a while and the regression hits something high-stakes. Do not lean on it if that version is near deprecation. Use the window to repair the scaffolding and build a test set.
4. Does switching between GPT, Claude, and Gemini mean rebuilding the agent?
Partly. Your logic and tools carry over, but the scaffolding usually does not, because tool formats, prompt sensitivity, and refusal behavior all differ. Never switch models in the middle of a live conversation.
5. Why did my agent work in testing but break in production after the update?
Testing runs on clean inputs and short conversations. Production has messy inputs, long histories, and expired tokens. An update often exposes context bloat or fragile parsing that only shows up under real load.
6. My agent runs inside another tool that updated. Is that a model problem?
Almost never. When an agent breaks right after an IDE or platform update, the cause is usually dropped authentication or a changed integration. Re-authenticate and check that tool’s release notes first.
7. How often do model updates actually break agents?
Often enough to plan for. Providers move models and aliases several times a year, and every unpinned agent is exposed each time. Pinning plus a test set turns each update into a scheduled task.
The Bottom Line
If your AI agent stopped working after a model update, it did not get dumber overnight. A model changed underneath scaffolding that was tuned to the old one, nothing errored, and the drift ran quietly.
Roll the model back to confirm, find the layer that actually broke, then pin your version and keep 20 to 50 real test tasks.
That is the boring work that keeps the next update from becoming an incident.