
Ask a chatbot what you told it five minutes ago in a new session. It has no idea. Ask a properly built AI agent the same question a week later, and it should still know.
That gap is memory. It’s the real difference between a chatbot that answers a question and an agent that runs part of your business.
Quick answer: A context window is the text a model sees during one exchange, and it resets when the session ends. AI agent memory is a separate system that writes information out of that window and retrieves it later, across sessions. Working memory holds the current task, episodic memory holds what happened before, semantic memory holds facts that stay true, and procedural memory holds how to do a task. Most agents only need the first two.
Key Takeaways
- A context window resets every session. Memory is a separate system, built to survive the reset.
- Mem0’s own benchmarking found consolidated memory beating plain vector search by roughly 26% on accuracy.
- Letta’s LoCoMo benchmark found an agent that just stores full transcripts in files scored 74% accuracy, competitive with specialized memory tools.
- Most agents don’t need every memory type on day one. Matching depth to the actual use case is what keeps a build affordable.
- The real failure point isn’t week one. It’s month two, once stale and contradicting facts compete for the same answer.
- A memory system that confidently invents an answer is more dangerous than one that admits it doesn’t know.
What “Memory” Actually Means for an AI Agent
Memory is information that survives past the current exchange and gets pulled back in later. It lives outside the model, usually in a database.
A language model remembers nothing between calls on its own. Whatever “memory” a product shows you is infrastructure built around the model, not a property of the model itself.
Memory is also part of what separates a true agent from simple no-code automation: a workflow trigger doesn’t need to remember anything, it just fires once.
The useful business question isn’t “does it remember.” It’s three sharper questions:
- What specifically does it remember?
- For how long does it stay accurate?
- What happens the moment that memory is wrong?
Context Window vs. RAG vs. Memory: The Distinction Everyone Confuses
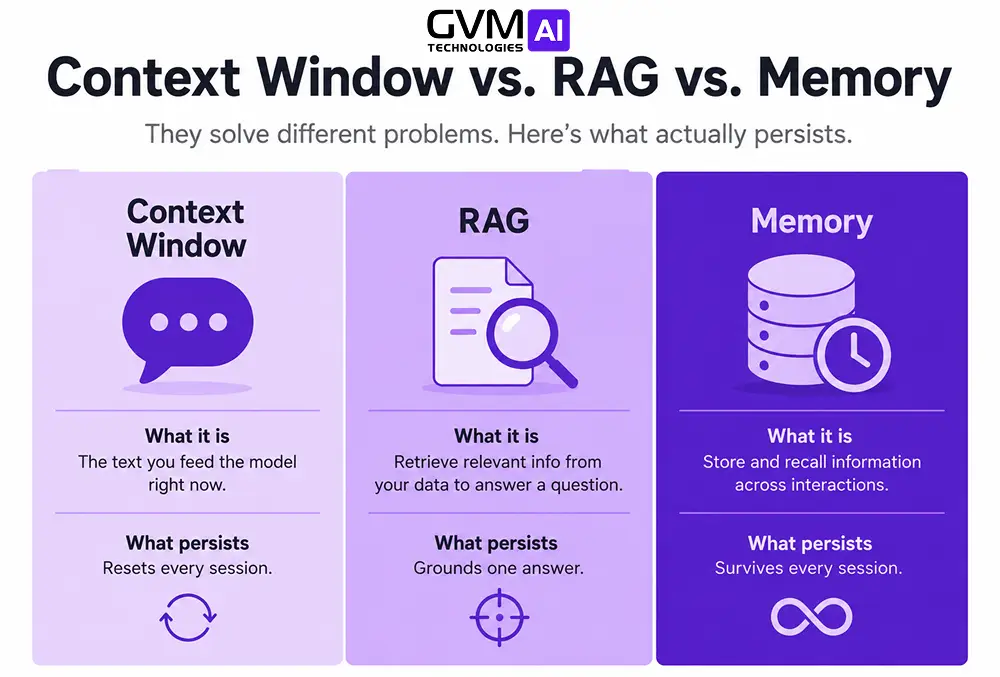
These three terms get used interchangeably in sales decks. That’s where most confusion starts.
1. What the Context Window Holds
The context window is the text a model sees in one call: instructions, the conversation, and anything retrieved for that turn. It’s temporary space, not storage.
2. What RAG Adds
Retrieval-Augmented Generation pulls documents from an outside source into that window before the model answers.
It doesn’t know who you are or what happened last time.
3. What Memory Adds
Memory retrieves the agent’s own history with a specific person or account, then feeds it back in. It’s what lets an agent say “since your last order was delayed, I’ve flagged this one for priority shipping.”
| Layer | What it holds | Resets when | Best for |
|---|---|---|---|
| Context window | The current exchange | Every new session | A single response |
| RAG | External documents, retrieved fresh | It’s stateless per query | Grounding facts in a knowledge base |
| Memory | The agent’s history with this user | Only if explicitly deleted | Continuity across sessions |
The Four Types of Memory an AI Agent Actually Uses
This breakdown maps cleanly onto what a business agent needs to do its job.
1. Working Memory
The current message and the last few exchanges. It lives inside the context window and disappears once the session closes.
2. Episodic Memory
What actually happened: a specific ticket, call, or order, tagged with a timestamp and outcome. A voice agent handling repeat callers depends on this.
3. Semantic Memory
Facts that stay stable, like your return policy or pricing tiers. Unlike episodic memory, it isn’t tied to one interaction.
4. Procedural Memory
The agent’s playbook: the steps for a refund, the escalation rule, the order a lead gets qualified in. It’s what lets multiple coordinated agents work as a team.
The Memory Tier Ladder: How Much Memory Your Use Case Needs
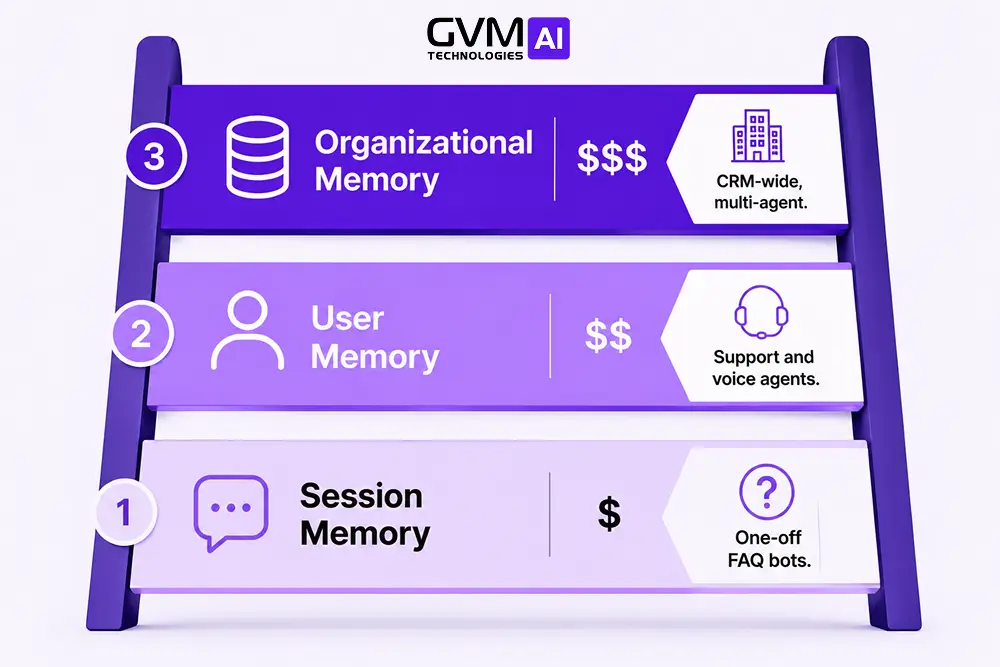
Not every agent needs all four types running at once. Treating memory depth as a ladder is how you avoid overbuilding.
| Tier | Covers | Typical use case | Cost |
|---|---|---|---|
| 1: Session | Working memory only | A one-off FAQ bot | $ |
| 2: User | Episodic + semantic, per account | Support, booking, voice agents | $$ |
| 3: Organizational | All four types, shared | CRM-integrated, multi-agent operations | $$$ |
1. Tier 1: Session Memory
Sufficient for simple, low-stakes cases where nothing needs to carry over between conversations.
2. Tier 2: User Memory
Most support and booking agents businesses deploy sit here. Continuity per customer is where the return shows up fastest.
3. Tier 3: Organizational Memory
The full stack, shared across agents and synced to your CRM. This is where the build-versus-buy question gets serious.
Why the Simplest Memory System Often Wins
Most vendor pitches skip this, because it undercuts the sale. On a widely used long-term recall benchmark, an agent that simply stores transcripts as flat files scored 74% accuracy.
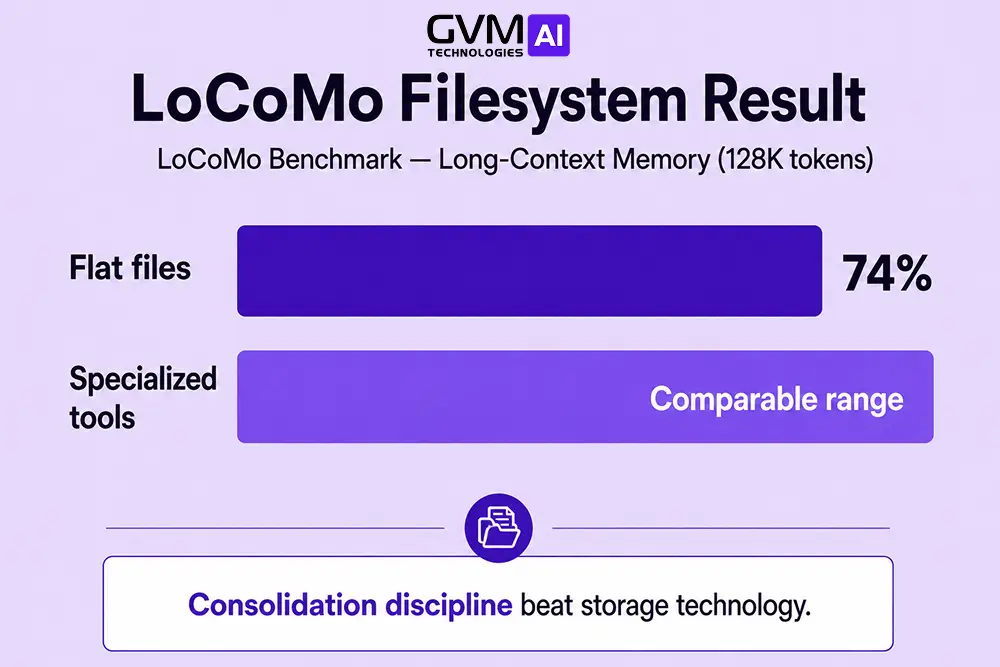
That held up against agents running dedicated vector and graph-based tools, per Letta’s published benchmark. The storage layer mattered less than expected.
What actually predicted quality was how well the system decided what to keep, and how it resolved conflicting facts. Neither is a database feature.
Worth knowing before anyone sells you on “the most advanced memory database.”
What Breaks After Month Two: The Consolidation Problem
Memory systems rarely fail in week one. They fail once enough history piles up that the agent starts retrieving the wrong version of the truth.
1. Why More Storage Isn’t Better Memory
Adding storage without a pruning strategy just delays the failure. The fix isn’t a bigger database, it’s deciding at write time what actually deserves to persist.
2. Contradictions: Why Recency Is the Wrong Default
A fact stored yesterday isn’t automatically more accurate than one stored a month ago, it’s just more recent. Treat the old fact as superseded, not deleted, so the agent can explain why it changed.
3. Negative Memory: What Didn’t Work
Most systems only log what succeeded, so an agent can retry a failed approach because nothing told it not to. Storing a failed attempt is often worth more than storing a fact.
Recall vs. Fabrication: The Test Nobody Runs
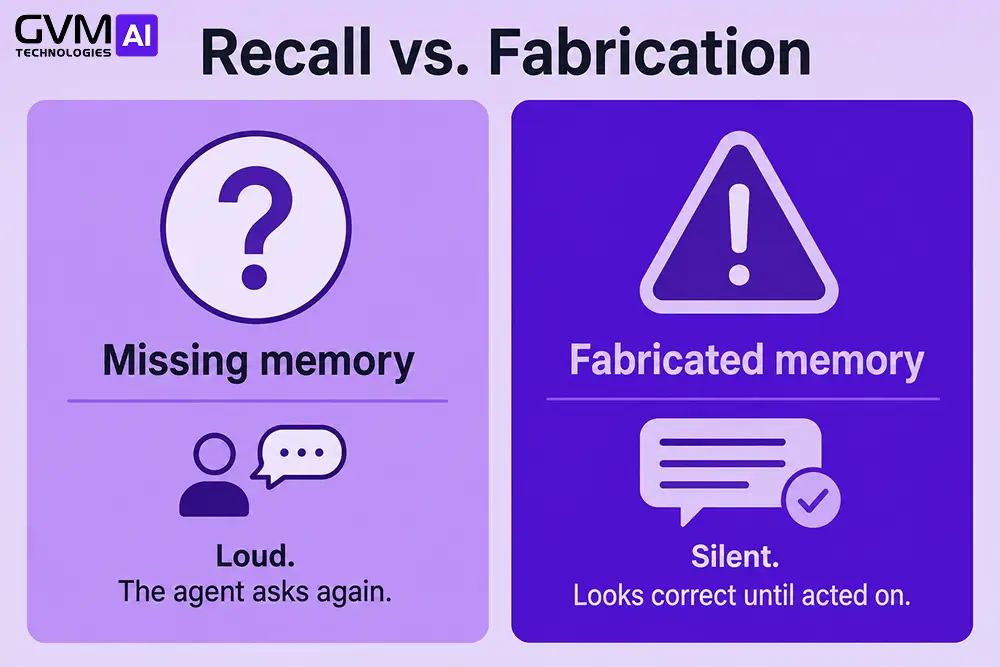
Every memory demo tests one thing: ask about something it was told, and see if it comes back. That only proves recall works.
It doesn’t test the more dangerous failure: a system asked about something it was never told, that answers anyway with false confidence.
A missing memory is loud, the agent asks again. A fabricated one is silent, and looks correct until someone acts on it.
Before trusting a system, run it through questions it was never given answers to:
- Ask 10 to 15 questions with no stored answer.
- Count how often it admits it doesn’t know versus guesses.
- Treat any confident wrong answer as worse than a missed recall.
This ties directly to the grounding failures behind most production hallucinations. A “no source, no answer” rule belongs in memory too.
The Forget-or-Keep Test: What Deserves to Become Memory
Before anything gets written into long-term memory, run it through four questions. Answer fewer than three with confidence, and it doesn’t get promoted.
- Will this still be true in 30 days? If not, it belongs in working memory, not a permanent record.
- Does losing it cost more than storing it? A one-time preference matters less than a compliance requirement.
- Can it be verified later against a source of truth? An unverifiable memory is a liability the moment it’s wrong.
- Is there a rule for which fact wins if it’s later contradicted? Without one, contradictions pile up unresolved.
Why Persistent Memory Becomes a Security Question
The moment memory persists across sessions, it stops being purely a feature and becomes an attack surface.
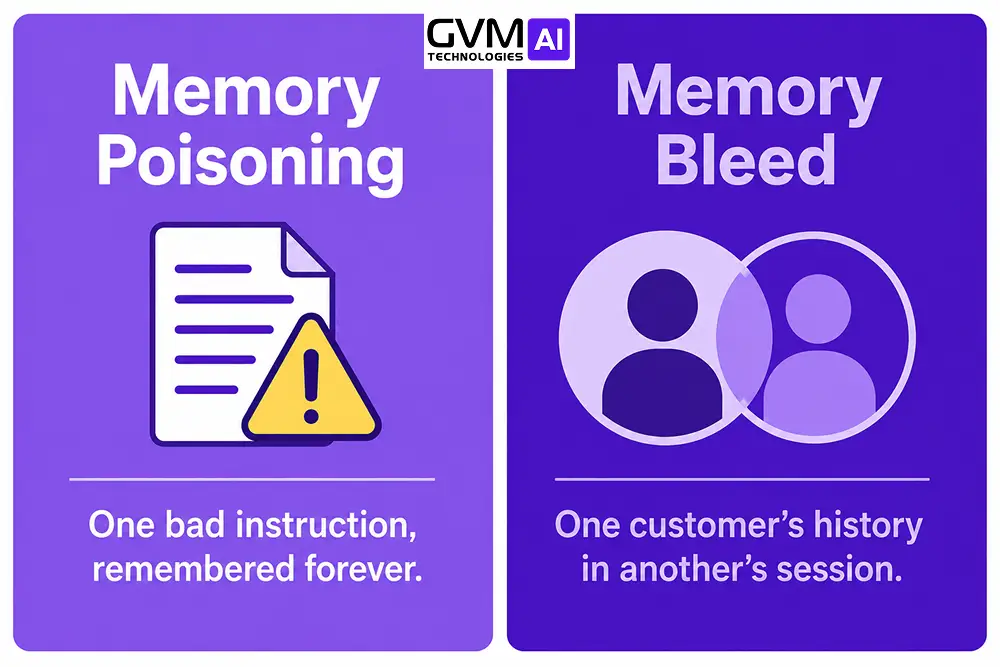
1. Memory Poisoning
If a hidden instruction inside a document gets written into memory, it doesn’t stop at one response. It can resurface in every future session.
This connects to the same action failures that cause agents to hallucinate in production.
2. Memory Bleed
In a multi-tenant system, memory scoped incorrectly can let one customer’s history surface in another’s session.
This is why customer data access and memory design need to happen together.
It’s the same discipline behind our shadow AI research.
Where Memory Actually Moves Revenue, by Industry
Memory only matters where continuity changes the outcome.
| Industry | What memory changes | Without it |
|---|---|---|
| Real estate | Agent recalls buyer criteria across sessions | Buyer re-explains budget every visit |
| Healthcare | Triage agent references symptoms already reported | Patient repeats history every call |
| E-commerce | Support agent sees the return already in progress | Customer describes the same issue twice |
| Professional services | Intake agent tracks submitted documents | Prospect resubmits paperwork and drops off |
What Adding Memory to an AI Agent Actually Costs
Cost scales with the tier you actually need, not with how advanced the pitch sounds.
| Factor | Session memory (Tier 1) | Long-term stack (Tier 2 to 3) |
|---|---|---|
| Timeline | 1 to 3 weeks | 3 to 8 weeks |
| Effort | Prompt design, basic retrieval | Storage architecture, PII redaction, access control |
| Ongoing cost | Minimal | Hosting, embeddings, periodic consolidation |
| Smallest team | 1 engineer | 1 to 2 engineers plus a security review |
This is exactly what a core AI solutions scoping call is built to catch before a dollar gets spent on the wrong tier.
Common Mistakes That Waste Budget on AI Agent Memory
- Calling a long context window “memory.” A bigger window still resets, no matter how many tokens it holds.
- Storing raw logs instead of extracted facts. Full transcripts in a vector store create noise, not memory.
- Skipping a pruning policy from day one. Retrofitting it later costs more than designing for it upfront.
- Trusting every retrieved memory equally. A high similarity score means related, not accurate.
- Skipping user-level isolation until after launch. Memory bleed is a design decision made too late.
Why GVM Technologies AI Builds Memory Into Every Agent We Deploy
Most agencies treat memory as an afterthought, bolted on once the agent already works. We treat it as part of the initial architecture, because retrofitting it later is where the real cost lives.
As an AI automation agency, we start by mapping which tier your workflow actually needs, using the Forget-or-Keep logic above, before a line of code gets written.
Before any build starts, you get:
- A scored breakdown of which memory tier your use case requires.
- A data isolation plan, so memory bleed is designed out, not discovered later.
- A consolidation policy, so accuracy holds at month six the same way it did at week one.
Ready to Build an AI Agent That Actually Remembers Your Business
An agent that forgets your customer’s history is a chatbot wearing a better interface. An agent that remembers wrong is a liability wearing a good one.
Talk to our team at GVM Technologies AI and bring us your actual workflow. We’ll tell you honestly which memory tier it needs, what it costs, and what to skip.
If you’re still validating whether your business is ready for an agent at all, our readiness checklist is the step before this one.
FAQs
1. Does an AI agent remember previous conversations by default?
No. Without a memory system built to store and retrieve past sessions, every new conversation starts from zero.
2. What’s the difference between memory and a longer context window?
A longer window holds more text in one session, but still resets when it ends. Memory is a separate system that survives the reset.
3. Is RAG the same thing as memory?
No, RAG grounds a single answer in outside documents, while memory retrieves the agent’s own history with a user. Many agents use both together.
4. How long should an agent keep a memory before it expires?
It depends on the fact. Stable details rarely expire, while a stated preference might need a 30- to 90-day accuracy review.
5. Can AI agent memory be a security risk?
Yes. Memory that persists across sessions can carry forward a poisoned instruction, or leak between accounts if isolation wasn’t built in from the start.
6. Do small businesses need long-term AI agent memory?
Often not the full stack. Most small businesses get the bulk of the benefit from Tier 2 user memory alone.
7. How much does it cost to add memory to an existing agent?
Session-only memory can be added in 1 to 3 weeks. A full long-term stack with access control typically runs 3 to 8 weeks.
The Bottom Line
A context window handles the current exchange, RAG grounds one answer in outside documents, and memory carries continuity across every session after.
Size memory to the tier your use case needs, and build a rule for contradicting facts. Test whether the system admits what it doesn’t know.
Get those right, and memory becomes the reason your agent feels like it knows your business.